BLOG
Notes on AI-native software quality.
Practical writing from the team behind TestingOps, RunningOps, CoverOps and ReplayOps.
AI sped up coding and moved the bottleneck to code review: what the Harvard study says
Data from 655 firms and 720,000 workers: AI agents raised lines of code by 44% while finished work rose only 13.7%. The gap piles up in code review, where time to approval grew 56%.
Read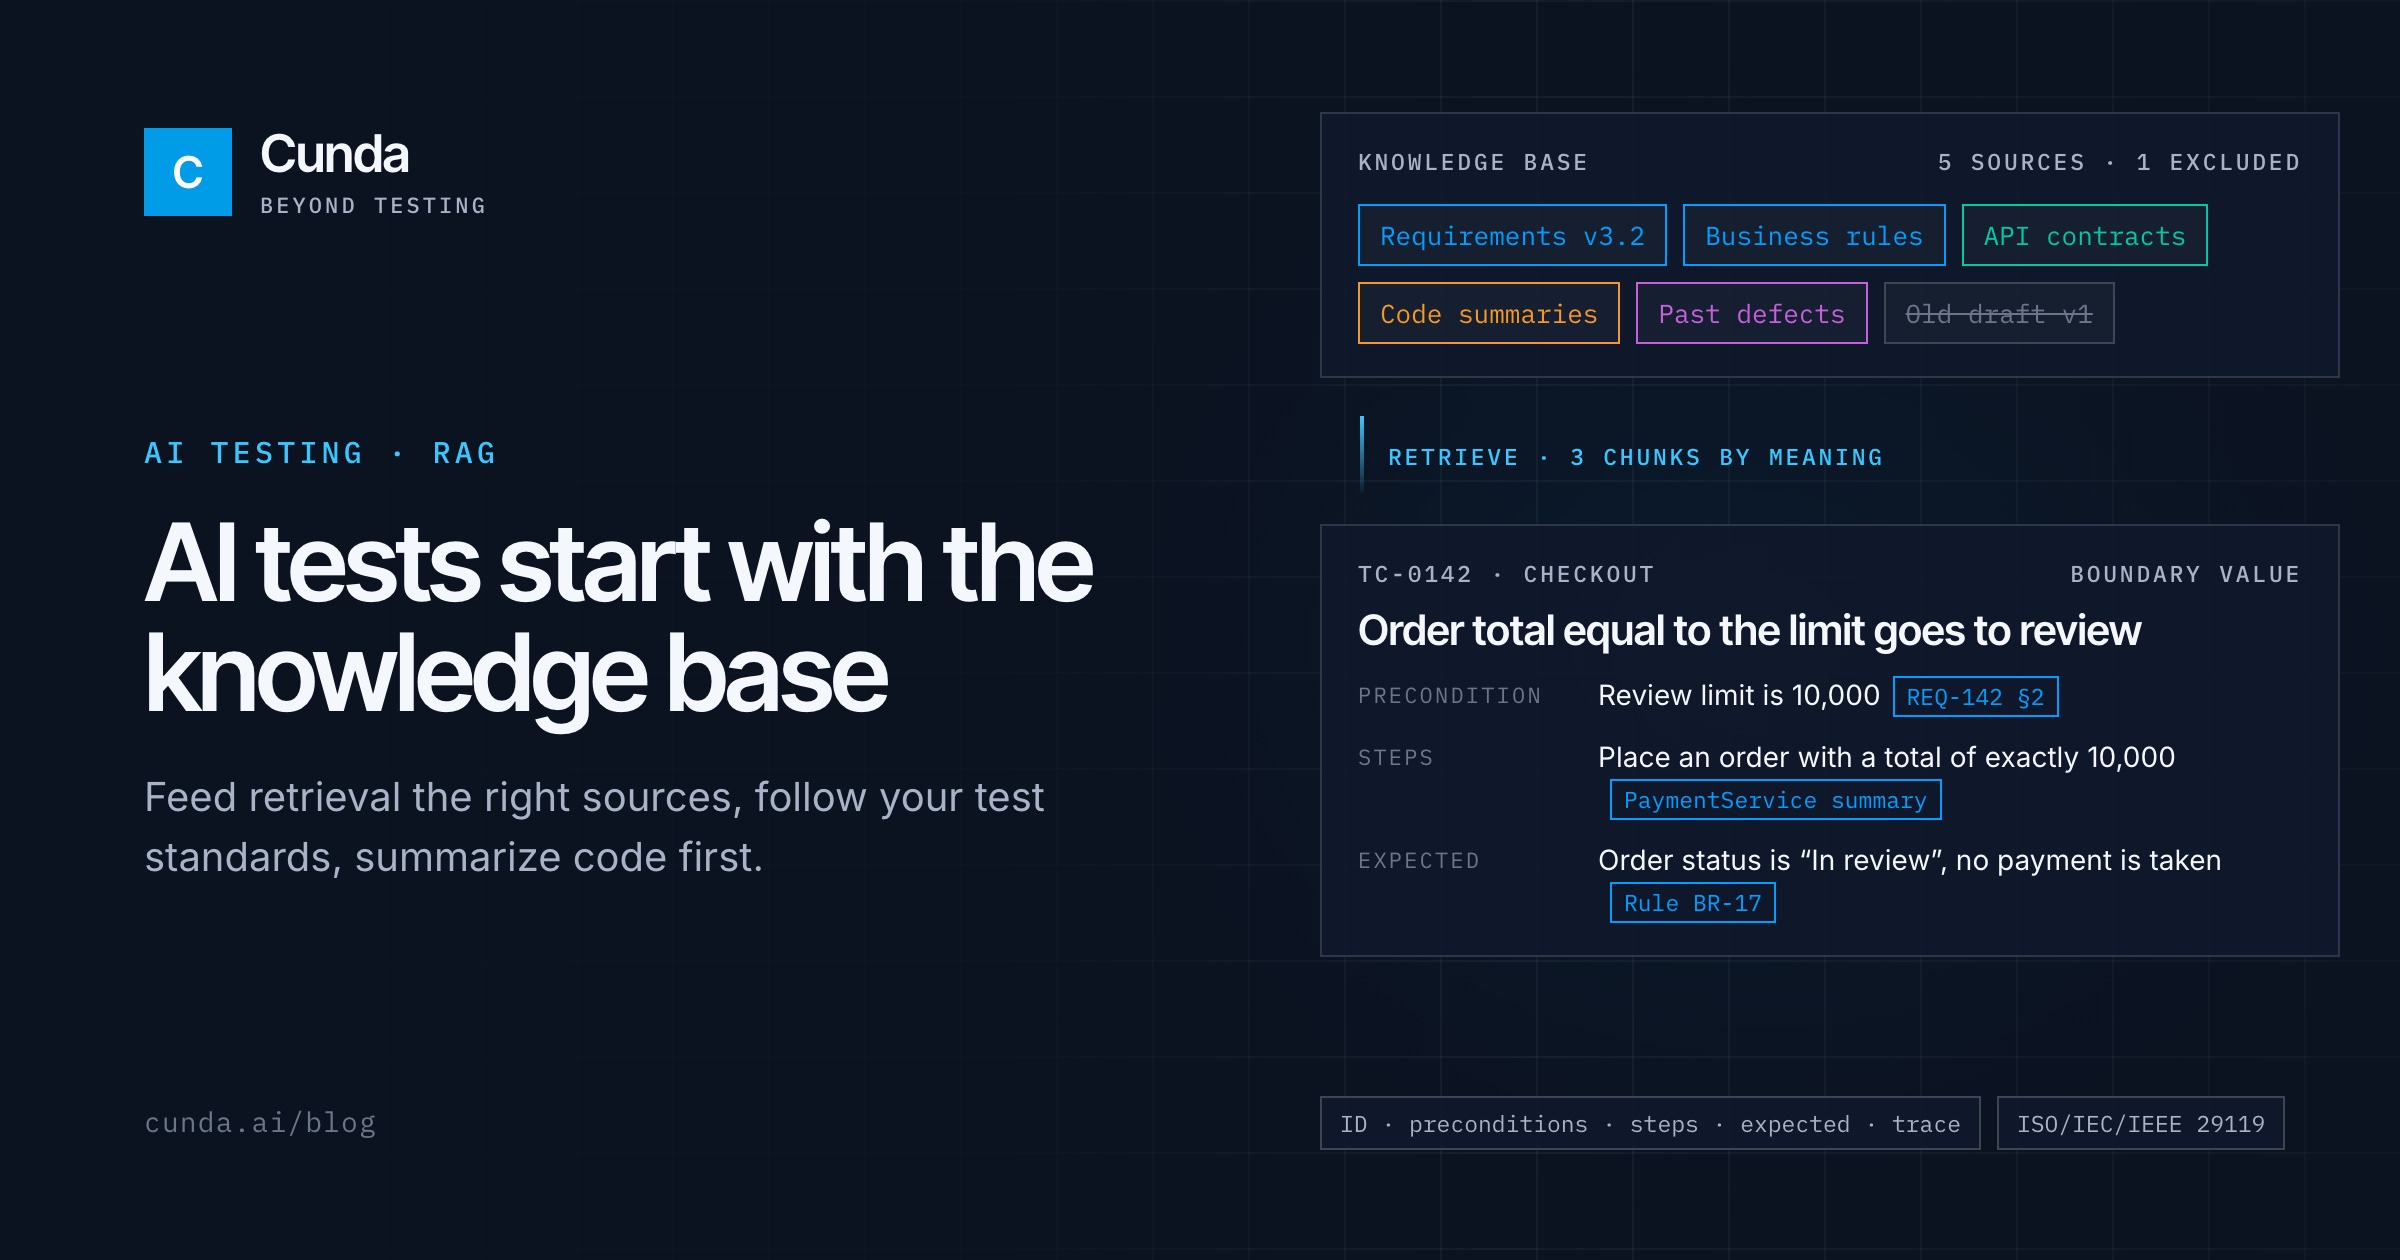
AI testing is only as good as its knowledge base: RAG, test standards and summarized code
A model that writes tests knows only what you give it. Three things decide the quality of AI testing: a knowledge base fed correctly through RAG, tests that follow your test standards, and source code summarized before it reaches the model.
Read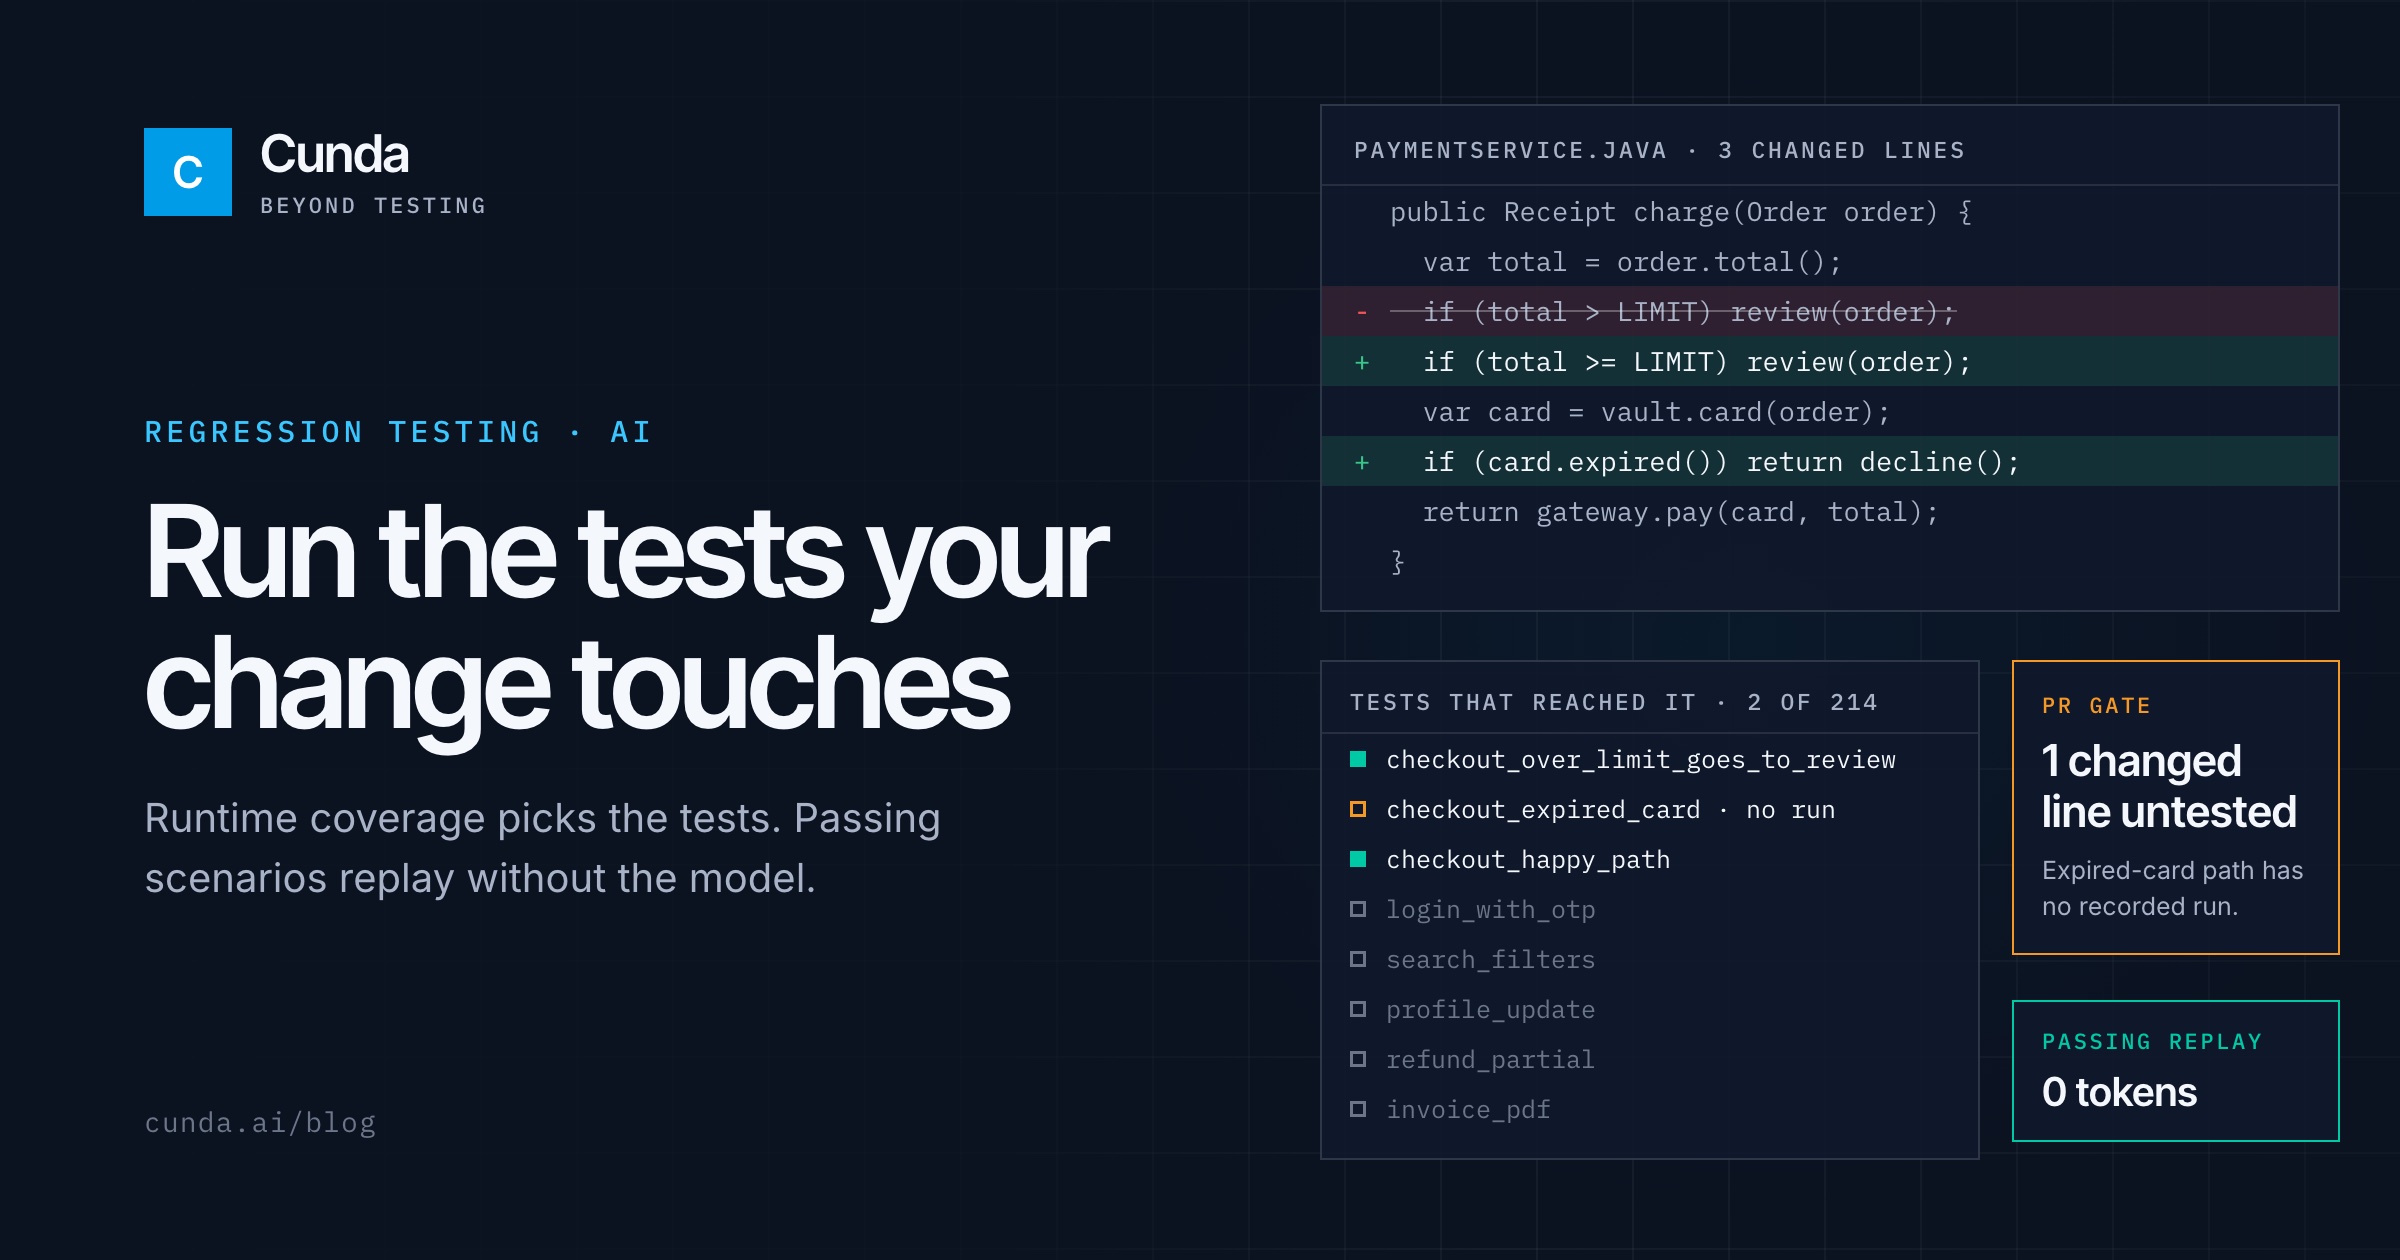
AI in regression testing: run the tests your change actually touches
Regression suites grow faster than anyone can maintain them. AI helps in three places: choosing tests by the code a change touched, keeping tests working when the product changes, and keeping the cost of running them flat.
Read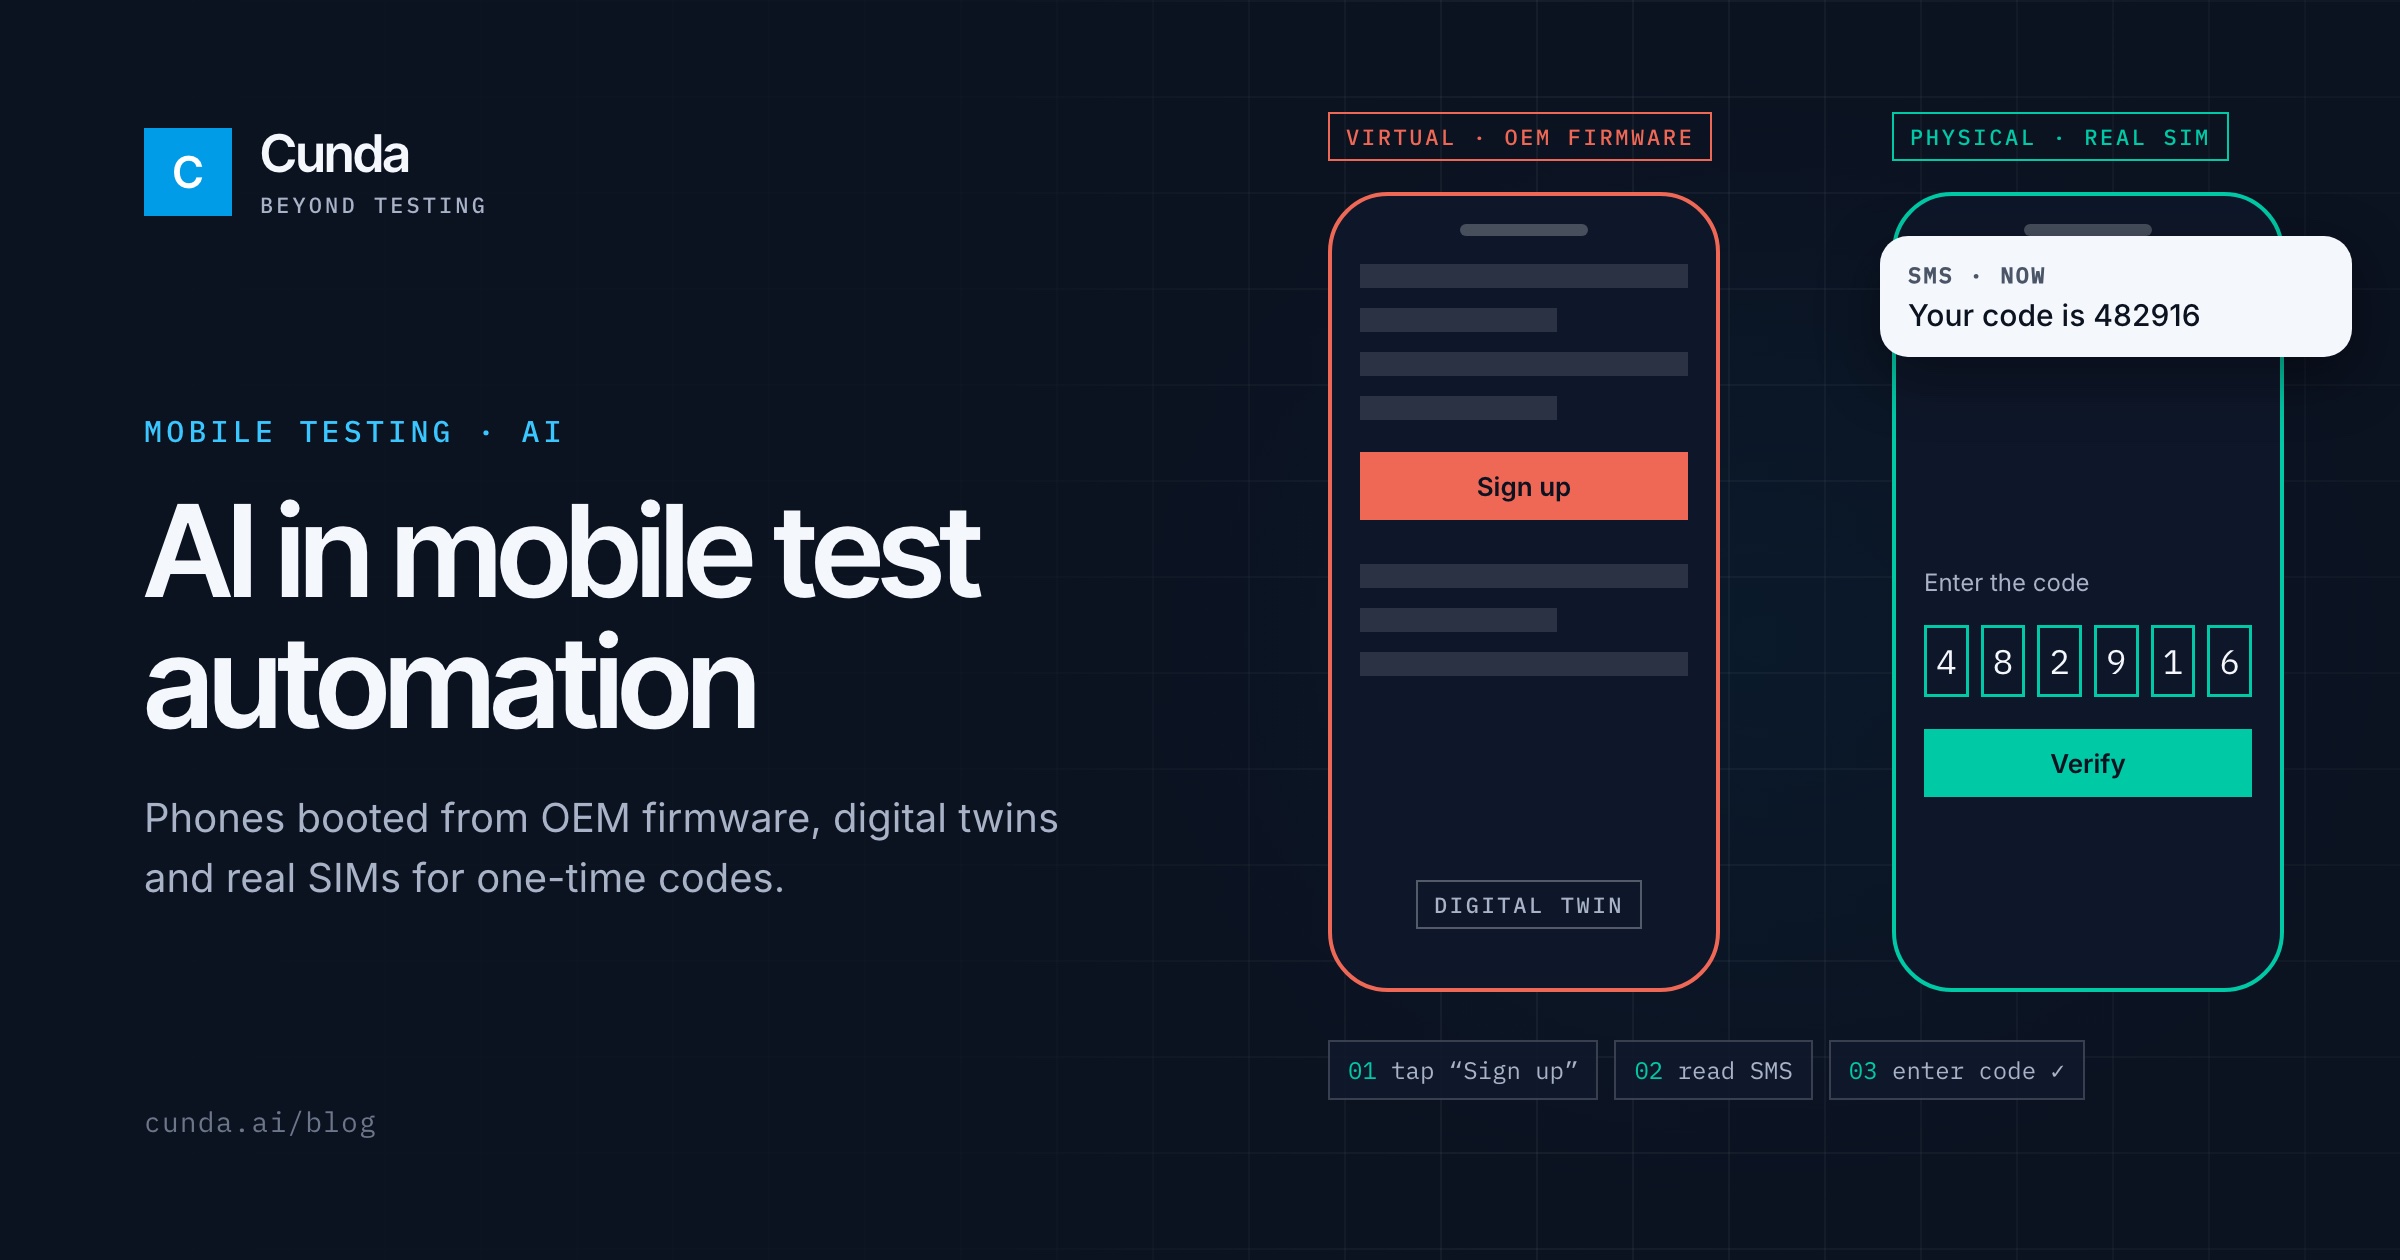
AI in mobile test automation: devices, one-time codes and digital twins
AI agents change how mobile tests are written, but the device and the SMS code still decide whether a flow can be tested. What agents add, where virtual devices and digital twins help, and when you need a real phone with a real SIM.
Read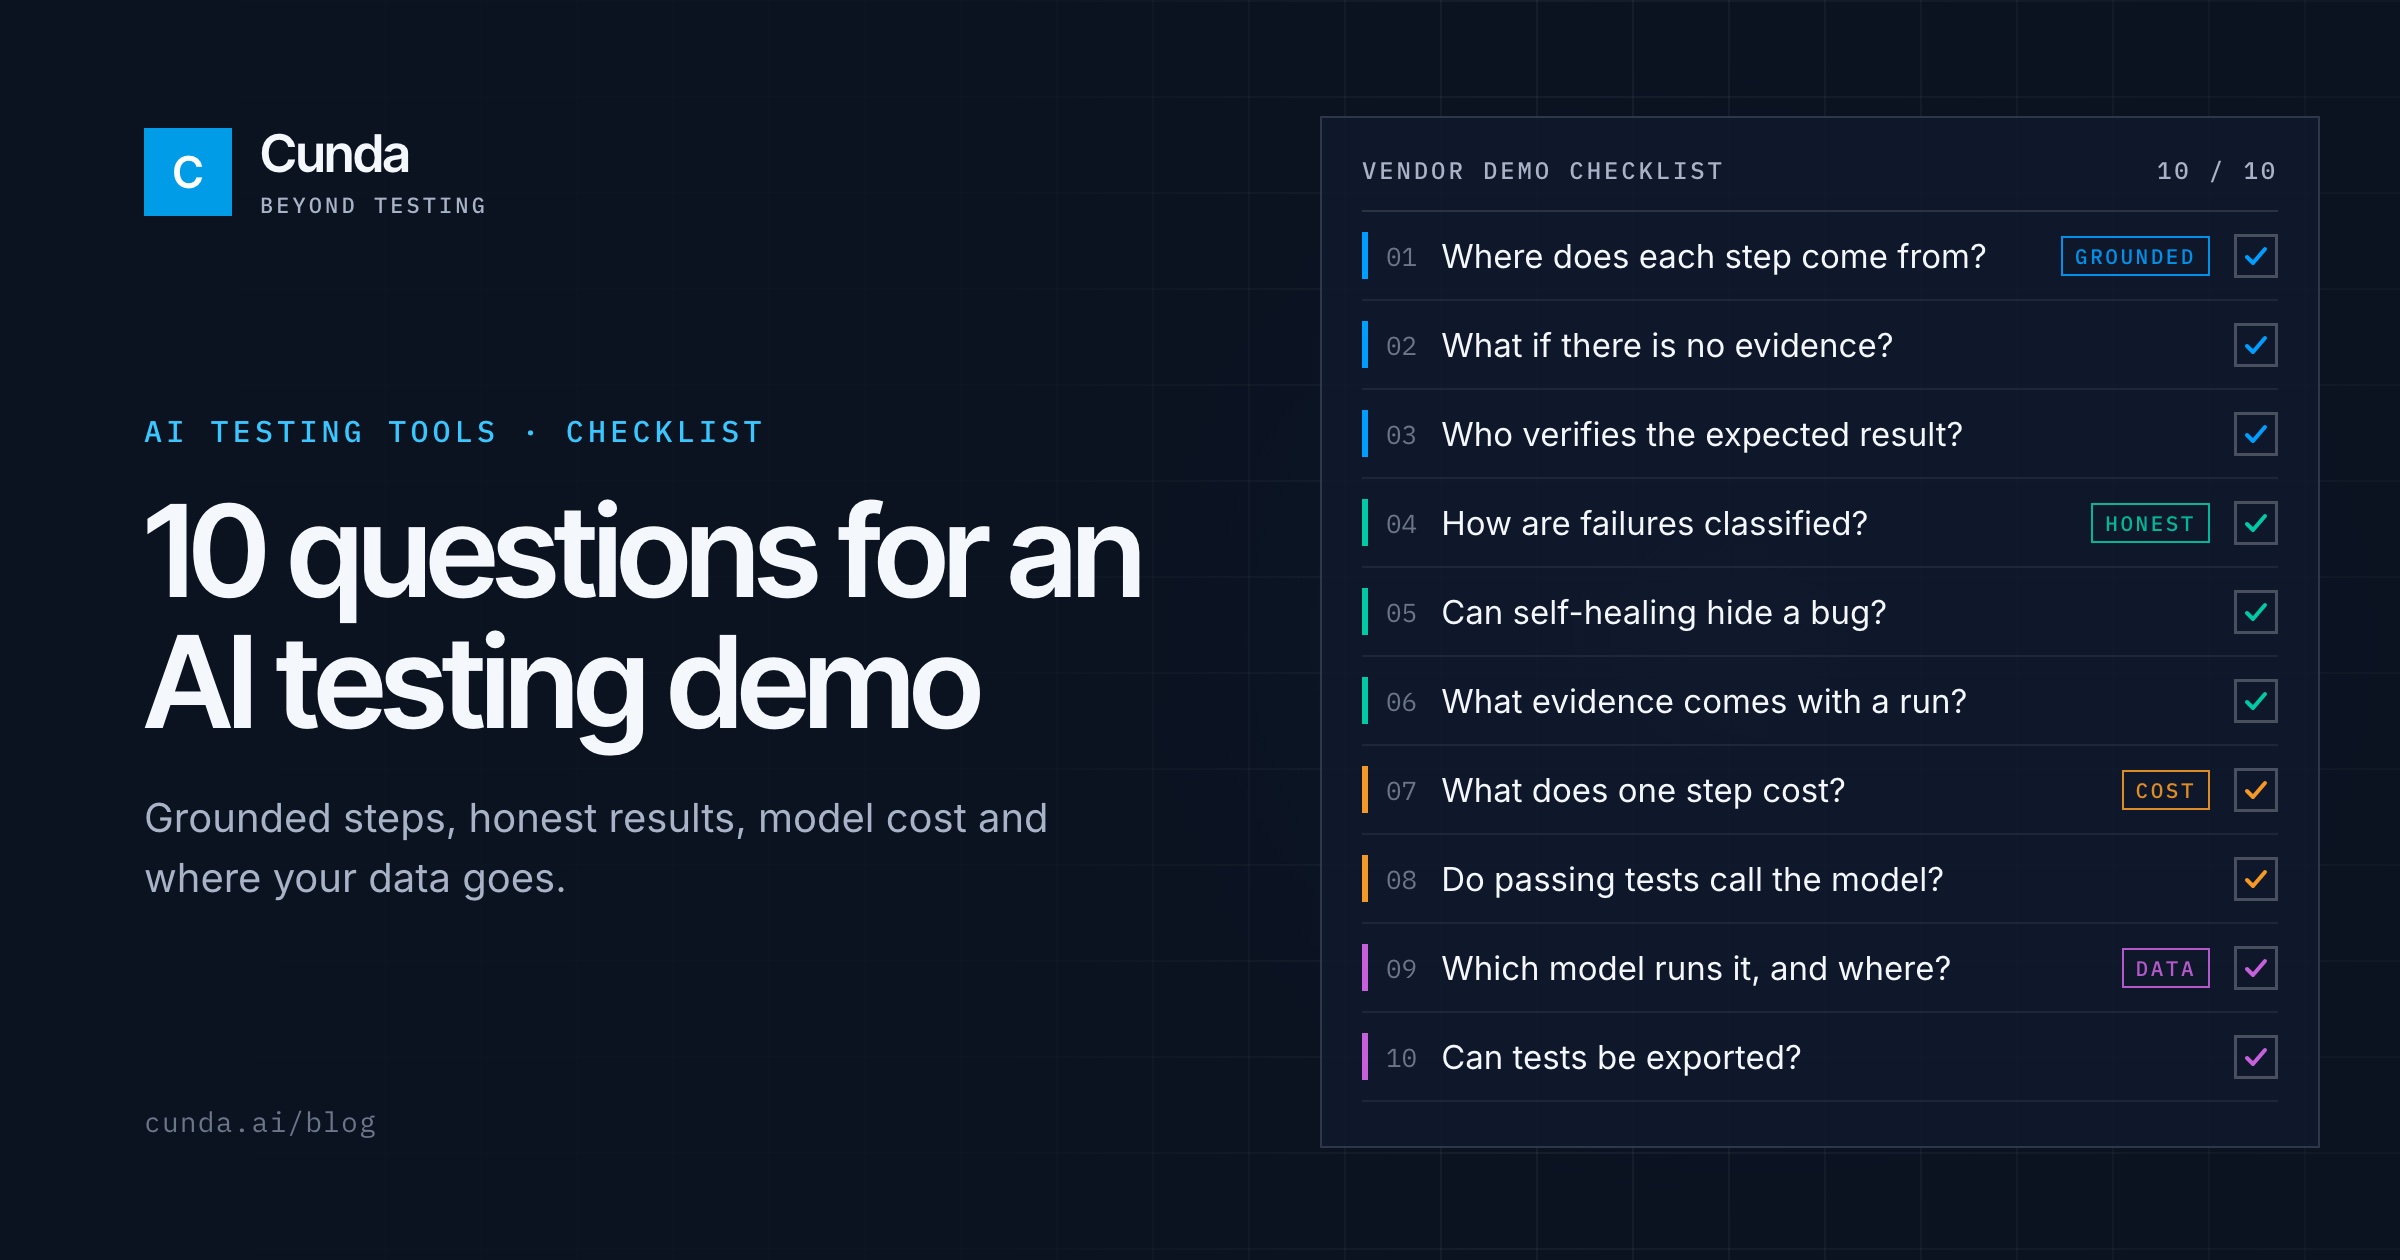
How to compare AI testing tools: 10 questions to ask in a demo
Almost every testing tool now says it uses AI. These ten questions show the differences in a demo: where each step comes from, whether a green result can be trusted, what a run costs and where your data goes.
Read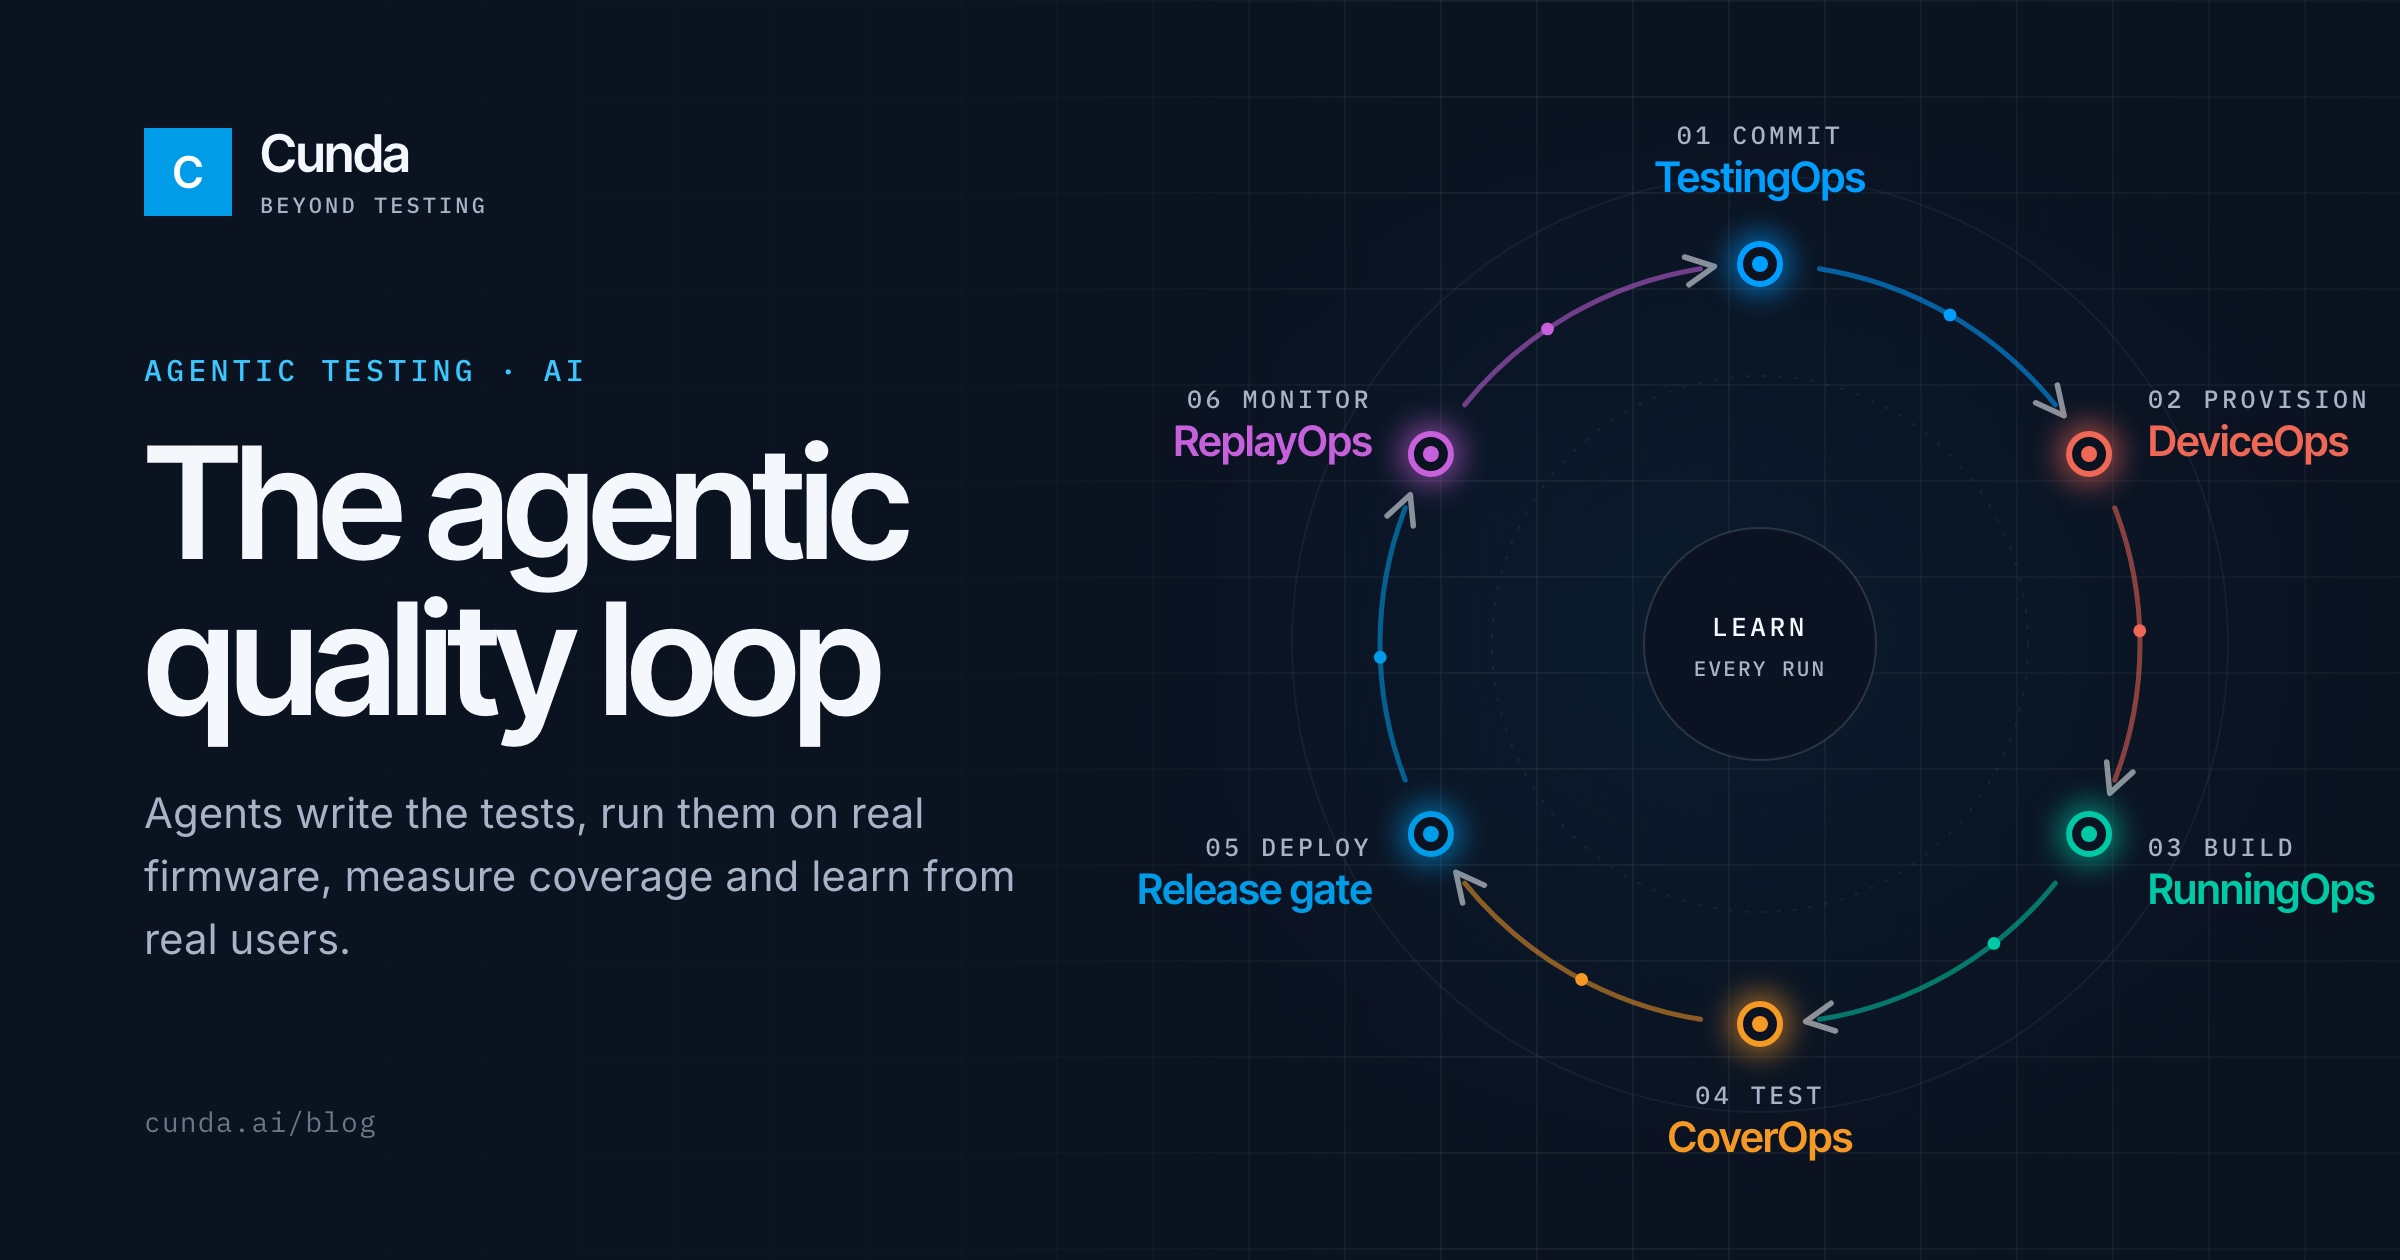
From test automation to an agentic quality loop: how Cunda works
Agents that produce the tests, virtual phones booted from real firmware, coverage measured on running services and real user sessions. How Cunda's five products come together in one quality loop.
Read